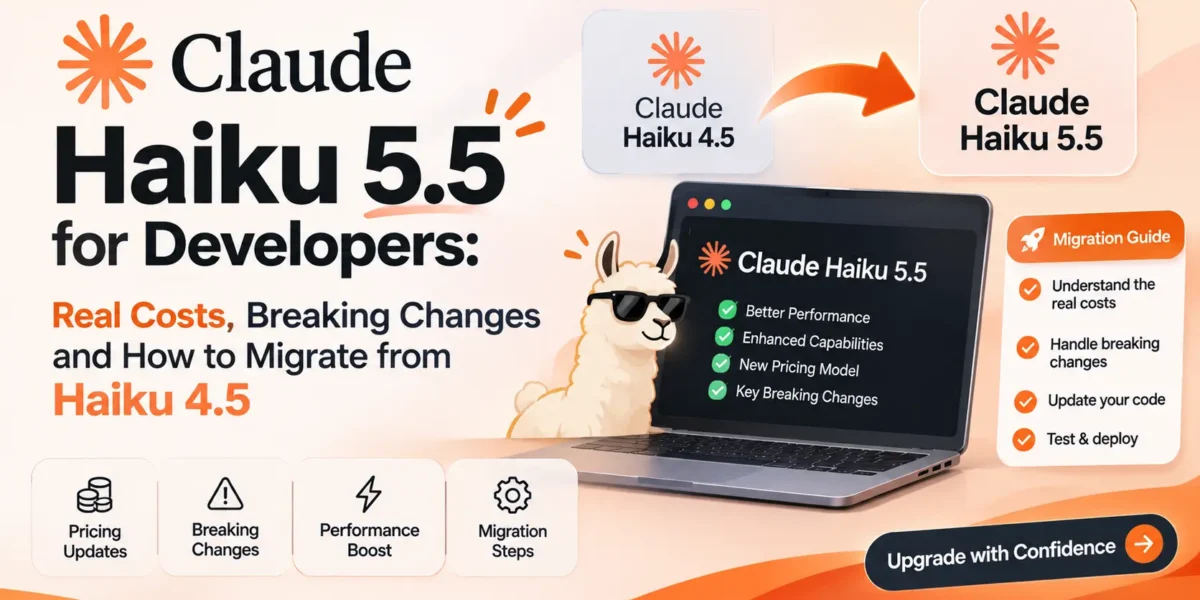
Anthropic released Claude Haiku 5.5 on October 7, 2026, and the headline is price: $0.10 per million input tokens and $0.50 per million output tokens for prompts up to 100,000 tokens, against $1 and $5 for Claude Haiku 4.5. The context window grows from 200K to 1M tokens and maximum output from 64K to 128K.
Haiku 5.5 is not a drop-in replacement, though. Several request shapes that worked on Haiku 4.5 now return a 400 error, thinking is on by default, and a new tokenizer changes every token count you have measured. This guide walks through what changed, what the real cost picture looks like, and the code changes a typical Haiku 4.5 integration needs.
What Haiku 5.5 is for
Anthropic positions Haiku as its model for high-volume, latency-sensitive work: classification, routing, extraction and sub-agent tasks inside larger agent systems. The specs from the official model overview:
| Claude Haiku 4.5 | Claude Haiku 5.5 | |
|---|---|---|
| Claude API model ID | claude-haiku-4-5 |
claude-haiku-5-5 |
| Context window | 200K tokens | 1M tokens |
| Max output | 64K tokens | 128K tokens (300K via the Batch API with a beta header) |
| Input price (per MTok) | $1 | $0.10 up to 100K-token prompts, $0.50 above |
| Output price (per MTok) | $5 | $0.50 up to 100K-token prompts, $2.50 above |
| Thinking | Manual, with budget_tokens |
Adaptive, on by default, controlled by effort |
| Minimum cacheable prompt | 4,096 tokens | 512 tokens |
The model is available on the Claude API, Amazon Bedrock (anthropic.claude-haiku-5-5), Claude Models on Google Cloud, Microsoft Foundry and Claude Platform on AWS. Note that claude-haiku-5-5 is a fixed ID with no date suffix and no separate alias. Its knowledge cutoff is June 2026, and Anthropic’s deprecations page lists its retirement as not sooner than October 7, 2027.
The real cost picture
The list price is roughly a tenth of Haiku 4.5’s for short prompts, but three things pull the actual saving down, and all three are documented by Anthropic.
1. The tokenizer counts about 30% more tokens
Haiku 5.5 uses the same newer tokenizer as Claude 4.7 and later models. Anthropic says the same input text produces approximately 30% more tokens than on Haiku 4.5, with the exact increase depending on content. Your usage numbers, token-counting results and max_tokens limits all shift. Large images also cost more, because Haiku 5.5 uses the high-resolution image tier: a 2,000 by 1,500 pixel image costs about 2.5 times as many visual tokens as on Haiku 4.5.
2. Thinking tokens are billed as output
Adaptive thinking is on by default, so a response can begin with thinking blocks even if your request never mentions thinking. Those tokens count toward max_tokens and are billed. In multi-turn conversations, thinking blocks from earlier assistant turns also stay in context as input tokens, which Haiku 4.5 did not do.
3. Long prompts switch to a higher price tier
A request whose prompt is over 100,000 tokens pays $0.50 input and $2.50 output for the whole request. The pricing page is specific that prompt length counts all input tokens, including cache reads and cache writes, so a mostly cached prompt can still cross the line. Combined with the tokenizer change, a prompt of around 77,000 tokens on Haiku 4.5 could land just over 100,000 on Haiku 5.5.
A worked example
Take a classification job of one million requests, each measured on Haiku 4.5 at 2,000 input tokens and 300 output tokens. These are illustrative numbers, not a benchmark:
- Haiku 4.5: 2,000M input tokens at $1 plus 300M output tokens at $5 = $3,500.
- Haiku 5.5, assuming 30% more tokens: 2,600M input tokens at $0.10 plus 390M output tokens at $0.50 = $455.
- Thinking: every 1,000 thinking tokens per request adds another $500 across the million requests.
Even with generous thinking, the short-prompt case stays far cheaper. The point is that you should measure with your own prompts rather than divide your current bill by ten. Count tokens with model set to claude-haiku-5-5 instead of reusing old counts. The Batch API’s 50% discount still applies on top, and cache hits cost $0.01 per MTok in the lower tier.
Breaking changes to fix before you switch
Anthropic’s migration guide lists the changes for a Haiku 4.5 codebase. These are the ones most likely to break a working integration.
Manual thinking budgets return an error
Sending thinking: {"type": "enabled", "budget_tokens": N} to Haiku 5.5 returns a 400 error. Replace it with adaptive thinking and choose an effort level:
// Before (Haiku 4.5)
{
  "model": "claude-haiku-4-5",
  "max_tokens": 16000,
  "thinking": { "type": "enabled", "budget_tokens": 8000 },
  "messages": [{ "role": "user", "content": "..." }]
}

// After (Haiku 5.5)
{
  "model": "claude-haiku-5-5",
  "max_tokens": 16000,
  "thinking": { "type": "adaptive" },
  "output_config": { "effort": "medium" },
  "messages": [{ "role": "user", "content": "..." }]
}
Sampling parameters must go
Remove temperature, top_p and top_k from your requests. Anthropic recommends steering behaviour through the prompt instead. If you used temperature: 0 to make a classifier more consistent, the more reliable replacement is structured output with an enum, shown below.
Assistant prefill is rejected
Ending messages with an assistant turn for the model to continue now returns a 400 error, even with thinking turned off. Many classifiers and JSON extractors used a prefill such as { to force a format. Use structured outputs instead, which put a JSON schema in output_config.format:
{
  "model": "claude-haiku-5-5",
  "max_tokens": 1024,
  "output_config": {
    "effort": "low",
    "format": {
      "type": "json_schema",
      "schema": {
        "type": "object",
        "properties": {
          "category": { "type": "string", "enum": ["billing", "bug", "feature_request", "other"] }
        },
        "required": ["category"],
        "additionalProperties": false
      }
    }
  },
  "messages": [{ "role": "user", "content": "Classify this ticket: I was charged twice this month." }]
}
For other prefill uses, the guide suggests asking for a direct answer in the system prompt (instead of prefilling to skip a preamble) and moving continuation text into the user message.
Responses can start with a thinking block
Code that reads response.content[0].text as the answer will break, because the first block may be of type thinking. By default those blocks come back with an empty thinking field and only a signature; set thinking: {"type": "adaptive", "display": "summarized"} if you want a summary. Either way, select blocks by type.
Other changes worth checking
- Refusals: Haiku 5.5 runs safety classifiers that can decline a request with
stop_reason: "refusal", and there is no server-side fallback. Handle it explicitly. - Small
max_tokens: a limit tuned for Haiku 4.5 can now stop withstop_reason: "max_tokens"after a thinking block and before any text. Raise the limit or lower the effort. - Computer use:
computer_20250124is rejected. On the Claude API and Google Cloud, move to thecomputer_toolset_20260801toolset; on Bedrock, usecomputer_20251124with thecomputer-use-2025-11-24beta header. - Append-only conversations: if you send thinking blocks back, changing the system prompt, tools or earlier messages invalidates them. On accounts created on or after August 31, 2026, that returns a 400 error by default.
- Multi-tenant replay: thinking blocks only work in the account that produced them or a linked account. Blocks replayed through another account are silently dropped.
- Priority Tier: not supported on Haiku 5.5, so plan capacity separately if you rely on it for Haiku 4.5.
Choosing an effort level
Effort replaces the old thinking budget as the main dial. Haiku 5.5 supports all five levels: low, medium, high, xhigh and max. Its default is medium, while most other Claude models default to high. Anthropic’s guidance for Haiku 5.5 in summary:
lowfor chat, short tool tasks and simple high-volume requests. In long agent prompts it is more likely to skip a search or stop early.mediumas the starting point for most work, including agentic coding.highfor knowledge work, longer agent tasks and strict instruction following.xhighormaxonly when your own evaluations show a gain. At that point, compare against Sonnet 5.5 ($2/$10 per MTok) on cost and speed.
To turn thinking off completely, send "thinking": {"type": "disabled"}. That works at high effort or below; at xhigh or max it returns a 400 error.
A migrated request in TypeScript
Here is a small ticket classifier using the official @anthropic-ai/sdk package (use a recent release so the newer request fields are typed). It reads the answer by block type and handles refusals and truncation:
import Anthropic from "@anthropic-ai/sdk";

const client = new Anthropic(); // reads ANTHROPIC_API_KEY

export async function classifyTicket(ticket: string): Promise<string | null> {
  const response = await client.messages.create({
    model: "claude-haiku-5-5",
    max_tokens: 2048,
    output_config: { effort: "low" },
    system: "Classify the support ticket as billing, bug, feature_request or other. Reply with the label only.",
    messages: [{ role: "user", content: ticket }],
  });

  if (response.stop_reason === "refusal") {
    return null; // log it and route to a human
  }
  if (response.stop_reason === "max_tokens") {
    throw new Error("Ran out of tokens; raise max_tokens or lower effort");
  }

  return response.content
    .filter((block) => block.type === "text")
    .map((block) => block.text)
    .join("")
    .trim();
}
Compared with a typical Haiku 4.5 version, there is no temperature, no assistant prefill, a generous max_tokens to leave room for thinking, and no assumption that the first content block is text.
A sensible migration plan
- Search your code for
claude-haiku-4-5,budget_tokens,temperature,top_p,top_k,content[0]and any assistant turns at the end ofmessages. - Recount tokens for representative prompts with the token-counting endpoint and
model: "claude-haiku-5-5", and check which requests now cross 100K. - Run your evaluation set at
lowandmediumeffort and compare quality, latency and cost per request, including thinking tokens. - Roll out behind a flag so you can route traffic back to Haiku 4.5 while it remains available. Anthropic’s deprecations page still lists Haiku 4.5 as active, with retirement not sooner than October 15, 2026. That date has passed without a deprecation notice, and Anthropic gives at least 60 days’ notice before retiring a model, but check the page before you depend on the fallback.
- Watch refusal and
max_tokensstop reasons in your logs for the first days of production traffic.
If you use Claude Code, Anthropic’s guide also mentions that the /claude-api migrate this project to claude-haiku-5-5 command can apply these changes for you. Review the diff as you would any other.
Should you switch?
For short-prompt, high-volume workloads such as classification, extraction and routing, the cost difference is large enough that testing Haiku 5.5 is worth the migration work, as long as you measure with its own token counts. For long-document jobs, check where your prompts fall against the 100K threshold before assuming savings. And if your integration depends on prefill, sampling parameters or manual thinking budgets, budget time for those code changes first, because each one fails with an error rather than degrading quietly.
Sources: Claude Haiku 5.5 migration guide, Claude Haiku 5.5 overview, Claude API pricing, Effort parameter docs, Structured outputs docs, Model deprecations, VKTR