Most developers use abstract syntax trees every day without seeing one. Your linter, formatter, bundler, TypeScript compiler, editor refactorings and code-modification scripts all start the same way: they turn your source code into a tree and work on the tree instead of the text. Once you understand that tree, a lot of tooling stops being magic, and you can start writing small tools of your own.
This guide explains what an AST is, shows real ones from Python and JavaScript, and walks through two practical uses: finding code patterns and safely rewriting code.
What an abstract syntax tree is
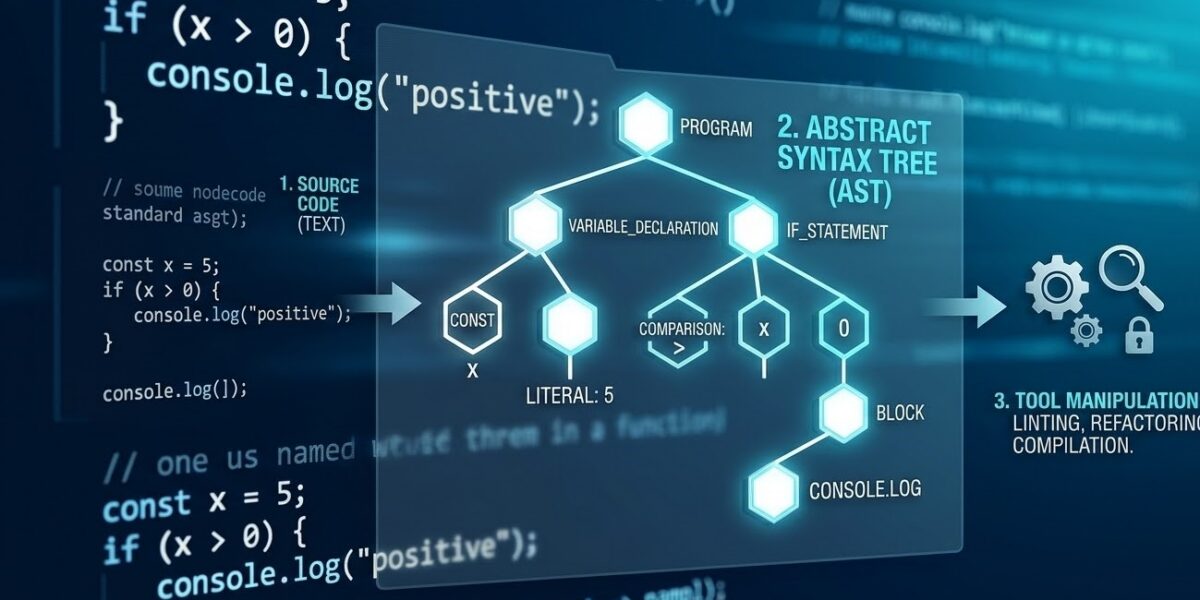
Source code is just text. To do anything useful with it, a tool first has to understand its structure: which parts are function calls, which names are variables, what belongs inside which block. An abstract syntax tree is that structure, represented as a tree of nodes.
It’s “abstract” because it leaves out details that don’t affect meaning, such as most whitespace, some punctuation and the exact placement of brackets. A concrete syntax tree (or parse tree) keeps every token, which is useful for tools that need to preserve formatting exactly, like some editors and formatters.
How code becomes a tree
Most parsers work in two broad stages:
- Lexing (tokenising): the text is split into tokens: keywords, names, numbers, strings, operators and punctuation.
total = price * 2becomes a name, an equals sign, a name, an asterisk and a number. - Parsing: the tokens are arranged into a tree according to the language’s grammar. The parser knows that
*binds more tightly than+, that an assignment has a target and a value, and so on.
If the parser hits something the grammar doesn’t allow, that’s a syntax error, which is why a missing bracket stops everything: without a valid tree, the tools have nothing to work on.
A real AST in Python
Python ships with an ast module, so you can look at a tree with no installs:
import ast
print(ast.dump(ast.parse("total = price * 2"), indent=2))
Running that on Python 3.11 prints:
Module(
  body=[
    Assign(
      targets=[
        Name(id='total', ctx=Store())],
      value=BinOp(
        left=Name(id='price', ctx=Load()),
        op=Mult(),
        right=Constant(value=2)))],
  type_ignores=[])
Reading it from the top: the module contains one statement, an assignment. The target is the name total, being stored to. The value is a binary operation: multiply the name price, being loaded, by the constant 2. Notice that the spaces and the = sign have gone. What’s left is the meaning.
A real AST in JavaScript
JavaScript tools mostly share a common tree format called ESTree. For const x = 5;, the tree contains a VariableDeclaration node with kind: "const". Inside it is a list of VariableDeclarator nodes, each with an id (an Identifier named x) and an init (a Literal with value 5).
The easiest way to explore these is AST Explorer. Paste in code, choose a parser (Babel, Acorn, TypeScript, and many parsers for other languages), and click on any part of the code to see the matching node. It’s the fastest way to learn what node types a tool will see.
Use 1: Finding patterns reliably
Suppose you want to find every call to print() in a codebase. A text search for print( also matches strings, comments and methods named print on other objects. An AST search only matches real calls:
import ast

class PrintFinder(ast.NodeVisitor):
    def visit_Call(self, node):
        if isinstance(node.func, ast.Name) and node.func.id == "print":
            print(f"print() call on line {node.lineno}")
        self.generic_visit(node)

source = '''
def greet(name):
    print("hello", name)   # this one counts
    message = "print(x)"   # this one is just a string
    return message
'''
PrintFinder().visit(ast.parse(source))
This prints print() call on line 3 and ignores the string on line 4. The NodeVisitor class walks the tree and calls visit_Call for every function call node. Calling generic_visit keeps it walking into nested nodes.
Use 2: Writing a lint rule
ESLint works exactly this way. Each rule tells ESLint which node types it cares about, and ESLint calls it as it walks the tree. Here’s a complete custom rule that flags console.log calls, using ESLint’s flat config format:
// rules/no-console-log.js
export default {
  meta: {
    type: "suggestion",
    messages: { noLog: "Remove console.log before committing." },
  },
  create(context) {
    return {
      "CallExpression[callee.object.name='console'][callee.property.name='log']"(node) {
        context.report({ node, messageId: "noLog" });
      },
    };
  },
};
// eslint.config.js
import noConsoleLog from "./rules/no-console-log.js";
export default [
{
plugins: { local: { rules: { "no-console-log": noConsoleLog } } },
rules: { "local/no-console-log": "error" },
},
];The long string is an ESLint selector, a CSS-like query over the AST: find CallExpression nodes whose callee is the property log on an object named console. Built-in ESLint rules are written the same way, which makes the custom rules documentation a good next read.
Use 3: Rewriting code safely
ASTs aren’t only for reading. You can change the tree and turn it back into code. This Python example renames a variable everywhere it’s used as a name, without touching comments or strings:
import ast

class RenameVar(ast.NodeTransformer):
    def visit_Name(self, node):
        if node.id == "tmp":
            node.id = "total"
        return node

tree = RenameVar().visit(ast.parse("tmp = 1\nprint(tmp + 1)\n# tmp stays in comments"))
print(ast.unparse(tree))
The output is:
total = 1
print(total + 1)
Notice that the comment has disappeared. Python’s built-in AST drops comments and formatting, so ast.unparse is fine for generated code but not for editing files people maintain. For real refactoring, use tools that preserve formatting: LibCST for Python, or jscodeshift and ts-morph for JavaScript and TypeScript. This is how large codebases run automated migrations, called codemods, across thousands of files.
Also note what this simple example doesn’t handle: scope. It would rename a different tmp inside another function too. Real refactoring tools track which names refer to which variables, which is a step beyond the raw AST.
Where else ASTs show up
- Transpilers and bundlers: Babel, SWC, esbuild and the TypeScript compiler parse code, transform the tree (removing types, rewriting modern syntax, eliminating unused code) and print it back out.
- Formatters: Prettier and Black parse your code and reprint it from the tree in a consistent style, which is why they can’t produce invalid code.
- Editors: syntax highlighting, code folding and “rename symbol” increasingly rely on incremental parsers like Tree-sitter, which update the tree as you type. Some editors, such as Ki (which we looked at separately), go further and let you select and move whole syntax nodes.
- Security scanners: tools like Semgrep and CodeQL search for dangerous patterns in the tree, for example user input flowing into a database query.
AST versus text tools
AST-based tools are more reliable than find-and-replace for code, but they aren’t perfect. They understand syntax, not intent: an AST knows that something is a function call, not whether the call is correct. And a transformation can produce valid code that behaves differently if it ignores scope or side effects. They’re a big improvement on regular expressions, not a guarantee of correctness. Run your tests after any automated change.
Where to go next
- Paste a few lines of your own code into AST Explorer and click around.
- Write a
NodeVisitorin Python that counts functions longer than 50 lines in a project. - Add one custom ESLint rule for a mistake your team keeps making.
- Try a small codemod with LibCST or jscodeshift on a throwaway branch.
After that, compiler and tooling internals look much less mysterious. It’s all trees.
Related reading
- Ki Editor: A Structural, Multi-Cursor Modal Editor
- The Three Pillars of JavaScript Bloat
- Migrating from Zig to Rust: When It Makes Sense
Sources: Python ast module documentation, ESTree specification, ESLint custom rules, AST Explorer, Tree-sitter.